What one blocked pick wave costs a $20M apparel brand during a drop
What does one blocked pick wave actually cost a $20M apparel brand during a drop?
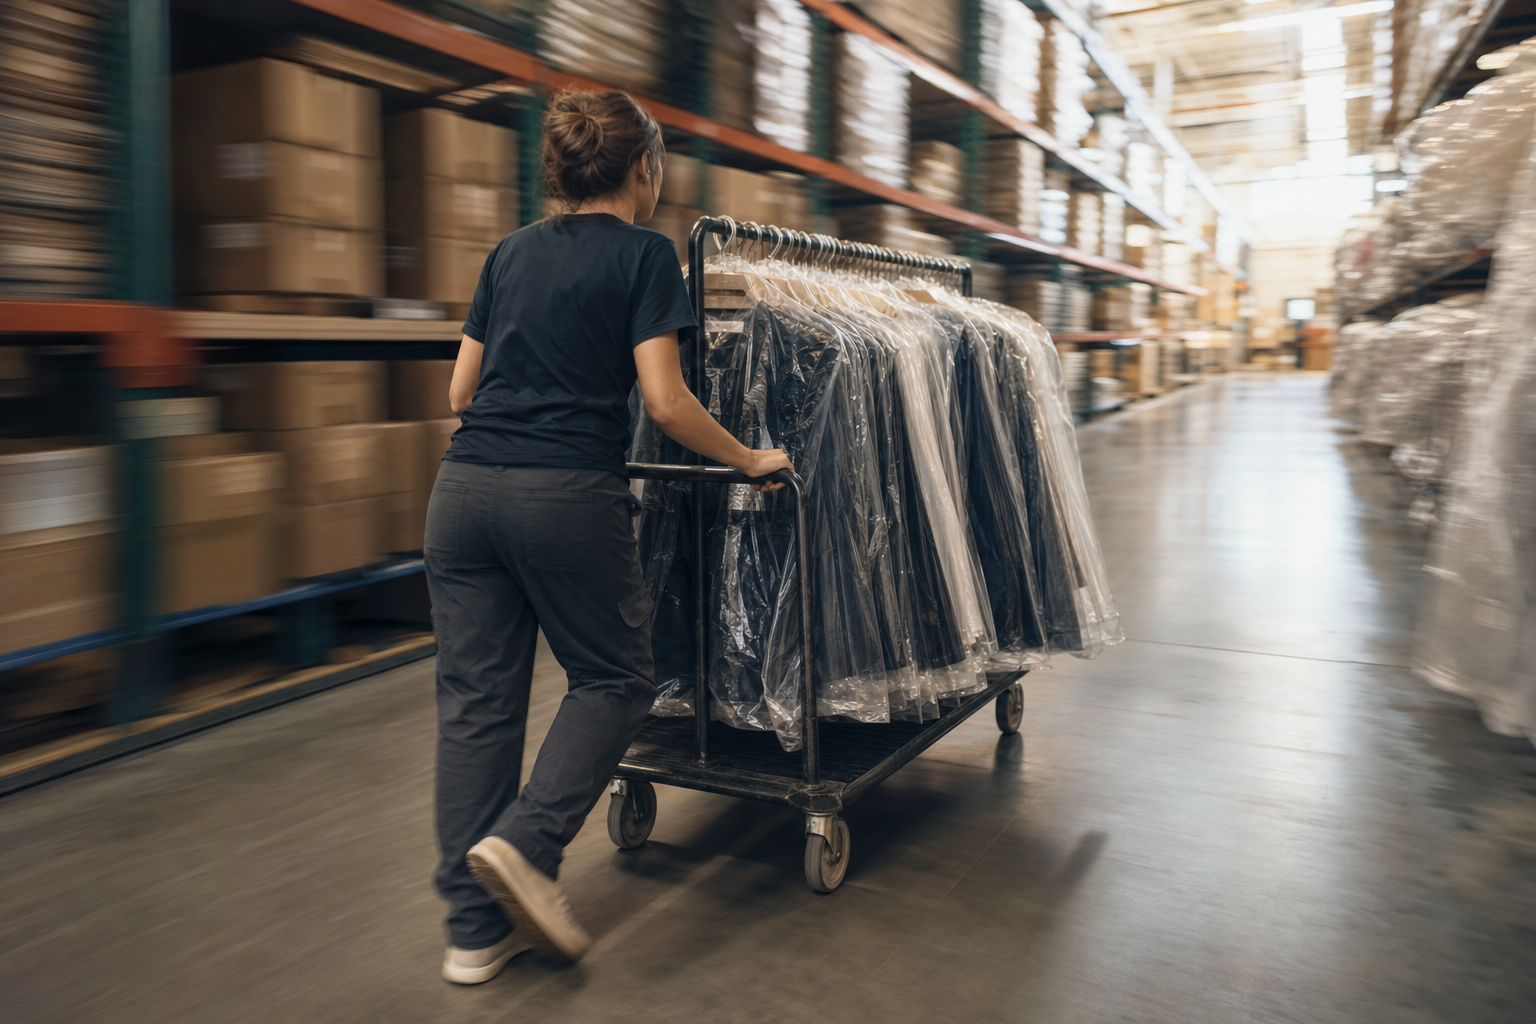
It is 10:40 AM on a Thursday drop day. The 3PL supervisor pings the ops lead: wave 3 is stuck. The pick list shows 480 units committed, the shelf count shows 431, and the WMS will not release the wave until someone resolves the variance. The ops lead opens Shopify, the ERP, and the 3PL portal in three tabs and starts counting. Pickers stand down. The CX queue begins to fill with order-status questions. A wholesale ASN that was supposed to go out at noon slips to end of day, which means it misses the retailer’s receiving window on Friday. One blocked wave, and the brand is now paying in four different currencies at once.
The blocked pick wave cost apparel warehouse teams quietly absorb during drops is one of the most expensive line items in the entire operation, and almost none of it appears on a warehouse invoice. It shows up as refunds, chargebacks, idle labor, and a reorder decision made with bad numbers two weeks later. This post walks through what a block actually costs a $20M wholesale-plus-DTC brand, why the block is almost never caused by the warehouse, and what the architectural fix looks like.
What is a blocked pick wave, precisely?
A pick wave is a batch of orders released to the floor together so pickers can walk the warehouse once and fulfill many orders in one pass. A blocked pick wave is a wave the WMS or 3PL system refuses to release, usually because committed quantities exceed available quantities on at least one SKU, because an order is missing required data (ship-to, carrier, packing list), or because an allocation rule cannot resolve (DTC pulling from a pool reserved for a wholesale PO, for example).
The block itself is a symptom. The cause almost always sits upstream in the order and inventory layer, which is why throwing more pickers at it does nothing. This is Breakpoint 5 of the 6 Breakpoints of Apparel Operations in motion: warehouse execution becomes less predictable not because the warehouse got worse, but because the data feeding it drifted.
Why do blocks cluster on drop days specifically?
Drop days compress a month of order volume into a window of hours. Three things happen at once that make blocks far more likely.
First, DTC order velocity spikes. A drop that moves 2,000 units in the first hour will generate 1,400 to 1,800 orders depending on units per transaction. Each of those orders writes to the same inventory pool the 3PL is picking against.
Second, wholesale shipments for the same season are usually in the same warehouse during the same week. The ATS logic has to distinguish between units committed to a buyer’s PO and units available to DTC, and if that distinction lives in a spreadsheet or in someone’s head rather than in the system, the first wave of DTC orders will quietly eat into wholesale-committed stock.
Third, the inventory count at the start of the day is almost never actually correct. For a $15M brand running wholesale, DTC, and a 3PL, we see 6 to 9 hours per week spent reconciling inventory across Shopify, the 3PL portal, and the wholesale system, and oversell rates of 2 to 3 percent at peak. On a drop morning that error compounds the moment the first wave releases.
In the vendor evaluations I run week to week, the pattern I keep seeing is that brands blame the 3PL for the block, the 3PL blames the ERP for bad data, and the ERP vendor points at the ecommerce platform. Everyone is partially right, which is another way of saying no single system owns inventory truth. That ownership gap is the actual problem.
What does a four-hour block actually cost on a $20M brand?
Let us walk the money. A $20M apparel brand doing a seasonal drop will typically push 15 to 25 percent of a season’s DTC volume through the first 48 hours of the drop. Call it a conservative 1,800 orders in the first day across DTC and wholesale pick-and-pack. A four-hour block on wave 3, which usually sits mid-morning, has four cost categories.
Direct refund and cancellation cost
When inventory variance resolves and the oversell is confirmed, somewhere between 40 and 120 DTC orders typically need partial or full refund. At an average order value of $140 for a mid-market apparel brand, and assuming 70 units need to be refunded, that is roughly $9,800 in direct revenue reversal. The brand already paid the payment processor fee, the pick fee at the 3PL, and in many cases the outbound label was already generated. Those costs do not come back.
Wholesale chargeback and ship-window exposure
If the blocked wave contained a wholesale ASN that misses the retailer’s receiving window, the chargeback exposure is usually 3 to 5 percent of the invoice value for a late ship, plus a separate ASN compliance chargeback if the EDI 856 was not transmitted within the required window. On a $40,000 wholesale PO that is $1,200 to $2,000 in direct chargebacks, and more importantly it damages the vendor scorecard that determines whether the retailer takes the next season. If retailer chargebacks are already running above 1 percent of wholesale revenue, the EDI integration is the problem, not the warehouse, and a blocked wave will make the ratio worse.
Idle labor and overtime
A 3PL pick team of 8 pickers standing down for four hours at a blended $28/hour fully loaded is $896 of direct idle cost that the 3PL will bill back through their minimum-guarantee or hourly-floor clause. The recovery shift, usually run as overtime that evening or the next morning, adds another $1,500 to $2,500 depending on headcount and the premium rate.
Reorder and buying decisions made on bad data
This is the cost nobody counts. When the blocked wave is finally resolved, the inventory numbers in the ERP, the WMS, and Shopify are reconciled to a point-in-time snapshot that is already stale by the time anyone looks at it. Two weeks later, when the buyer or planner runs the sell-through report to decide what to reorder, they are reading a number that was never actually trued up. The replenishment order is placed against a false baseline, and the next drop starts with the same drift. There is no clean dollar figure to put on this, but on a $20M brand making 6 to 10 reorder decisions a season, even a 5 percent error on reorder quantities moves hundreds of thousands of dollars of working capital in the wrong direction.
Add the four categories and a single four-hour block during a drop costs roughly $18,000 to $35,000 in hard money, plus the slow-moving damage to the reorder cycle. Most finance teams never see this number because the costs are scattered across refund reports, 3PL invoices, chargeback deductions on wholesale remittances, and buying decisions that cannot be reverse-engineered.
Why is more picker headcount not the fix?
Because the block is not a throughput problem. The pickers were not slow. The wave would not release.
This is the conversation I have most often with prospects who are trying to decide between adding warehouse labor, switching 3PLs, or changing their operating system. Switching 3PLs almost never fixes a block pattern that is caused by upstream data drift, because the new 3PL inherits the same bad inventory signal from the same ERP. Adding labor at the 3PL just means more people standing idle when the next wave blocks.
The fix lives in three places upstream of the pick face. First, channel-aware ATS: the system must know that 480 units of SKU X are reserved against wholesale PO 10234 and not available to the DTC pool, and it must enforce that at the moment the order is accepted, not at the moment the wave is released. Second, a single source of inventory truth that both the storefront and the 3PL read from, rather than two systems reconciled nightly by an FTE doing data plumbing. Third, allocation rules that resolve automatically when a conflict appears, with a defined priority order (wholesale commits first, DTC pre-orders second, DTC on-hand third, for example), rather than a human triaging each conflict in a Slack thread.
For brands running multi-warehouse or 3PL operations, this is non-negotiable, because the surface area for drift multiplies with every location.
How do you tell whether your blocks are a data problem or a warehouse problem?
A simple diagnostic. Pull the last 90 days of blocked wave incidents from your WMS or 3PL. For each incident, classify the root cause into one of four buckets:
- Inventory variance at the SKU level (count on shelf did not match system)
- Allocation conflict (DTC pulling from wholesale-committed stock, or vice versa)
- Missing order data (ship-to incomplete, carrier not selected, packing requirement unmet)
- Physical warehouse issue (SKU not in bin, damaged units, equipment down)
If buckets 1, 2, and 3 account for more than 70 percent of your blocks, you have a data problem, not a warehouse problem. In the mid-market brands I work with, the actual split is usually 85 to 90 percent upstream causes and 10 to 15 percent genuine warehouse issues. The warehouse is almost always the messenger.
The warehouse execution scorecard is a more structured version of this diagnostic if you want to run it quarterly rather than reactively.
What does the operating model look like when blocks stop happening?
A few concrete behaviors. The order management layer knows what is on the shelf in real time, not on a 15-minute batch sync. Allocation rules are codified in the system, not in a buyer’s head. The 3PL receives orders already allocated, with the correct inventory pool labeled, so the wave release is a mechanical act, not a decision.
When a wholesale ASN is due, the pick list for that PO is batched separately from DTC and prioritized against the retailer’s ship window, with the EDI 856 generated automatically on pack confirmation and transmitted within the compliance window the retailer requires. A drop day looks like a busy day, not a crisis day. The ops lead is watching throughput numbers, not reconciling three tabs.
The difference between those two realities is not a better 3PL and not more pickers. It is whether the order, inventory, and warehouse layers share a single operational spine or are three systems held together by a human doing reconciliation. Brands in the $10M to $20M range almost always hit this wall at the same time, which is why that band is the predictable breakpoint zone where tool consolidation starts to pay for itself. Replacing 3 to 5 disconnected tools and the spreadsheets between them with a connected apparel operations platform is usually what it takes to get the data layer honest.
The real cost is the drop you do not run
Most of the money a blocked wave costs is not in the four hours of the block itself. It is in what the brand learns to avoid afterward. Operations teams that get burned on a drop quietly start to pull back: smaller drop sizes, fewer SKUs released at once, longer cushion windows between the drop and the first wholesale ship, more conservative pre-order limits.
Every one of those adjustments is a reasonable response to the chaos, and every one of them caps the top line. The brand that could have run a 4,000-unit drop runs 2,500 to be safe. The buyer that would have reordered aggressively hedges. The pattern that looks like discipline from the inside looks like a growth ceiling from the outside, and it is almost always traceable back to a warehouse execution layer that cannot be trusted during peak. Fix the data spine and the drop sizes grow again on their own.
FAQs
Where is your operation on the 6 Breakpoints curve?
The assessment scores your apparel operation across all six breakpoints (product data, production, inventory truth, order flow, warehouse execution, reporting) and identifies which one is hurting you most.
Frequently asked questions
Where this fits in the Uphance platform
Shubham writes about evaluating ERP fit, assessing operational complexity, and how apparel brands can tell whether their current systems are helping or holding them back. As a Solutions Consultant at Uphance, he runs discovery conversations and fit assessments for apparel brands moving off patchwork stacks of PLM, PIM, inventory, and B2B tools. His articles cover ERP selection, vendor RFPs, comparison frameworks, and the operational signals that tell a brand it has outgrown spreadsheets and point solutions. He focuses on how mid-market apparel teams evaluate connected platforms against the cost of staying with what they have.
Lalith writes about operational reporting and analytics for apparel brands, covering how connected data across inventory, orders, fulfillment, and warehouse execution translates into reporting that supports real decisions. As Senior Product Manager for Reporting and Operational Analytics at Uphance, he builds the dashboards and KPI work that let finance and operations teams stop arguing over numbers and start running the business. His articles cover landed cost, COGS reconciliation, month-end workflows, margin analytics, and the data hygiene patterns that determine whether reporting can actually be trusted at the executive level. He argues that reporting becomes political only when the operational layer underneath it is fragmented.